AI agents & tooling · 2 October 2026
HSI experiment tracking: configurations, artefacts and reproducibility
Track HSI configurations, failed runs, seed aggregates and checkpoint provenance with an offline SQLite CLI and an honest fictional-run explorer.
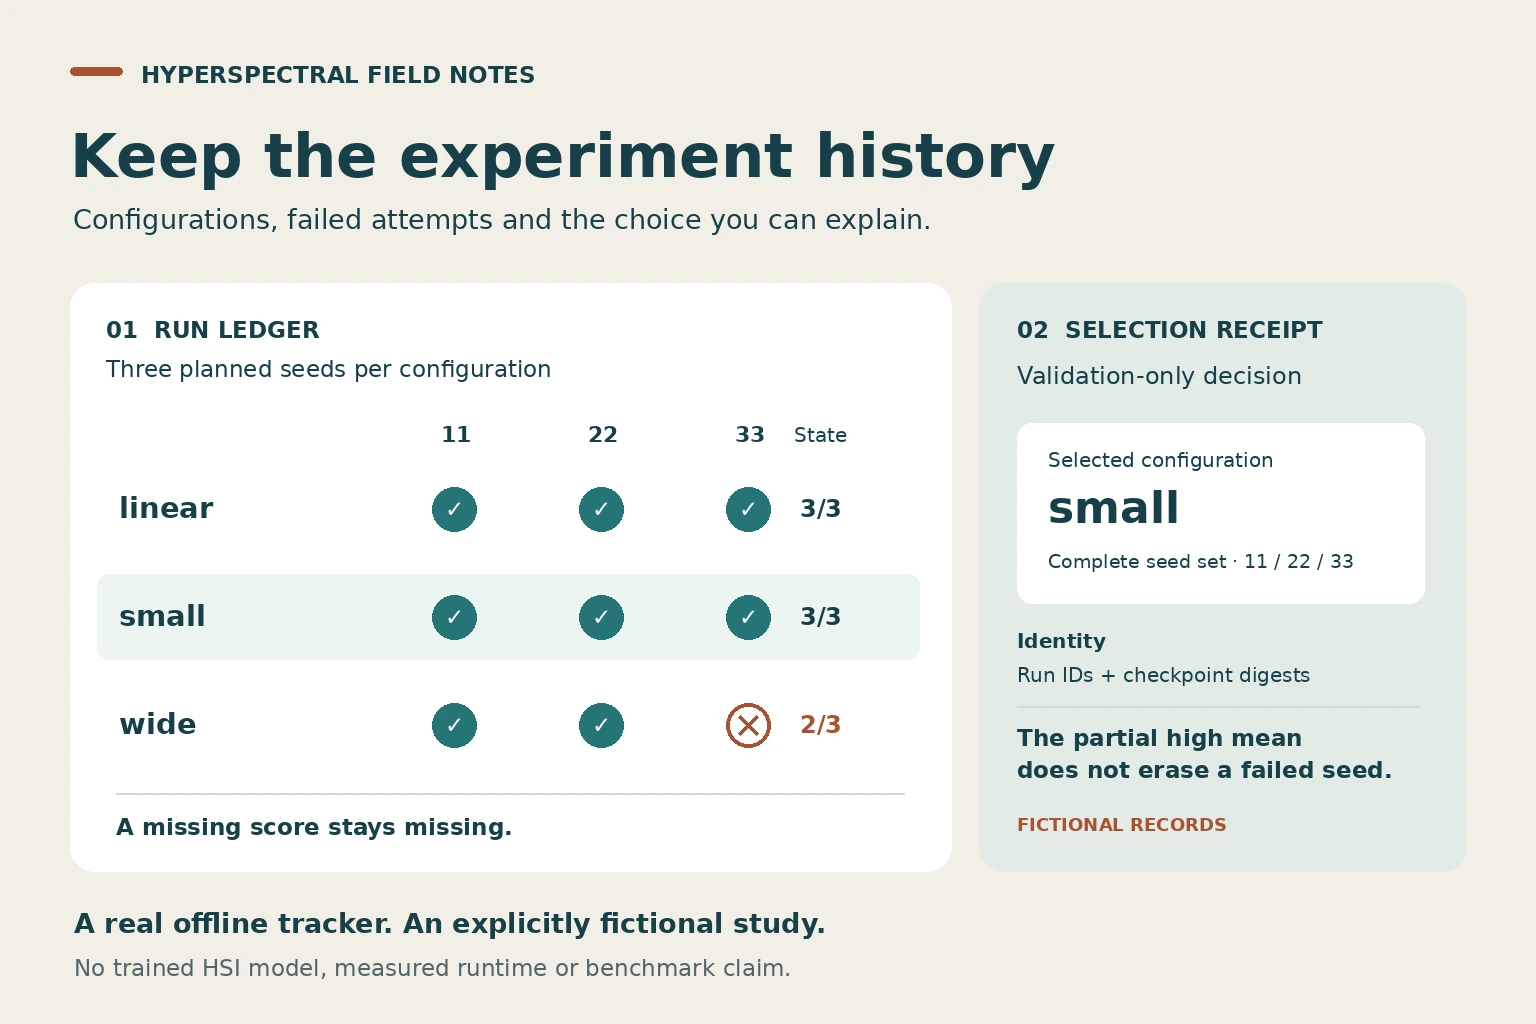
Original schematic built from explicitly fictional run records. Scores and resource costs are illustrative; no HSI benchmark is depicted.
Track the decision, not just the winning number
A folder called best_model is not an experimental record. Months later, it cannot explain which data were available, how many alternatives were tried, why a checkpoint was kept, or whether a promising configuration failed on its other seeds. In hyperspectral research, those omissions can change the scientific interpretation even when the saved accuracy is correct.
A reproducible pipeline describes how to execute an analysis. An experiment registry describes what happened across executions and how those observations led to a decision. This guide concentrates on that second layer: configurations, failed attempts, seed aggregates, checkpoint identity, selection provenance and resource accounting. It complements the pipeline capstone rather than rebuilding the same training workflow.
The companion is an actual local SQLite tracker written with the Python standard library. Its ten example records, validation scores, resource costs and checkpoint placeholders are explicitly fictional. No HSI classifier was trained to produce them. The software really validates, stores, searches, aggregates and locks those records; the numbers teach registry behavior rather than establish a benchmark.
Give the study, configuration and attempt different identities
An experiment is a bounded question under a declared evaluation protocol. A configuration is a resolved set of choices within that question. An attempt is one execution with a particular seed and an outcome. A retry is another attempt, not a second independent replicate. Keep these identities separate so that ten retries do not masquerade as ten independent seeds.
Save the resolved configuration, including defaults that actually took effect. Architecture, patch size, wavelength exclusions, optimizer, learning rate, augmentation, batch size and stopping rules belong there when they affect the result. Hash a canonical serialization of that configuration and retain the original readable file. A short nickname helps people; it should not be the sole identity of the analysis.
The example uses an immutable run ID and a configuration SHA-256. Reusing a run ID is rejected rather than overwriting a row. A new attempt for an already failed configuration and seed must point to its predecessor. Once that configuration and seed has a completed result, a second completed attempt is rejected. This intentionally strict teaching rule prevents cherry-picking retries; a production registry can support richer retry policies if they are declared and reported.
Treat HSI provenance as part of the comparison key
Two runs with the same tensor shape may not have the same inputs. Record scene and acquisition identifiers, sensor, processing level, radiance or reflectance units, wavelength centres and units, bad-band masks, label ontology, invalid-pixel handling and the version of any external reference labels. A changed class map can invalidate a comparison without changing a single model parameter.
For spatial methods, preserve the actual split membership and the spatial support used to construct each example. Centre-pixel disjointness is insufficient when training and validation patches overlap. Liang and colleagues examine this evaluation problem for spectral-spatial HSI classifiers. Keep split unit, patch support and buffering decisions close to the run, rather than relying on a sentence in a notebook. [1]
The registry stores digests for data, split, fitted-transform and environment artifacts, plus code reference, normalization fit scope, pretraining access, patch radius and buffer metadata. It refuses selection across differing protocol objects. This is a consistency check, not a geometric audit: a reported buffer of four pixels does not prove disjoint footprints, and a checksum does not prove a correct split. Save the separate leakage-audit outputs as additional artifacts in a real study.
If unlabeled target imagery is permitted for adaptation, name that access policy explicitly. Do not pool a transductive run with a strict unseen-scene run merely because their metric has the same name. The bundled tracker deliberately accepts train-only normalization; adapting it to another valid protocol requires a conscious schema and evaluation change.
Keep failed and cancelled attempts in the ledger
A failed run is not a zero-accuracy model. It has no valid final score unless the protocol defines a usable evaluation before the failure. Replacing missing scores with zero distorts the mean; dropping the row hides the failure rate and compute spent. Preserve status, failure category, a concise reason and the resources consumed before termination.
Distinguish a numerical failure, an out-of-memory failure, a user cancellation and an infrastructure interruption. These may imply different remedies. A controlled timeout can reveal a method’s cost under a resource budget; a broken storage mount usually says little about model quality. Both belong in the attempt history, with conclusions appropriate to what actually happened.
The example accepts completed, failed and cancelled terminal records. Completed records require a validation score and checkpoint artifact. Failed or cancelled records require a reason and an empty final-metric object. Intermediate learning curves can be retained separately; they should not silently substitute for the final score required by the comparison policy.
This small implementation ingests terminal records. It does not launch jobs, send heartbeats or discover a process that died before writing its record. In a production workflow, reconcile scheduler job IDs against the registry, and record stale or missing outcomes explicitly. Tracking infrastructure can fail too; an empty dashboard is not evidence that no experiments ran.
Aggregate the recorded seed plan before choosing a configuration
Choose the replicate plan before inspecting results and store it with the protocol. Distinguish training initialization seeds from split seeds, label-budget draws and independent sites. Three initializations on one fixed scene measure a narrower source of variability than three geographically independent evaluations. Do not label either quantity simply “uncertainty” without saying what varies.
For n completed seed scores, the registry reports their arithmetic mean and sample standard deviation, using the n−1 denominator. With fewer than two scores the sample standard deviation is unavailable. A mean plus or minus one sample standard deviation is a spread summary, not a confidence interval and not a significance test. Spatially correlated pixels are not independent replicate runs.
The fictional wide configuration has scores 0.81 and 0.72, but its third planned seed failed. Its observed mean is 0.765, higher than the small configuration’s complete three-seed mean of about 0.747. The registry displays that partial summary while marking it ineligible under the exact-seed-set policy. The small configuration becomes the eligible winner. This is a lesson about the decision rule, not evidence that small models outperform wide ones.
Incomplete configurations remain in the selection receipt with their missing seeds. Excluding them does not make failure irrelevant: explain why the result is conditional on successful completion and report the failed attempts. If the protocol instead assigns a budget-based failure penalty or reruns infrastructure failures, define that policy in advance and implement it consistently. Never invent a rule after seeing which model it favors.
Lock validation selection before accepting test results
A test score becomes a selection signal as soon as it influences which architecture, checkpoint, preprocessing variant or seed you keep. Renaming that column after the fact cannot restore a held-out evaluation. Cawley and Talbot show how optimization of a noisy model-selection criterion can itself overfit and bias subsequent performance estimates. Recording the search process makes this risk visible; it does not eliminate it. [2]
The tracker accepts only val_macro_f1 in tuning records and only validation as the selection split. Selection maximizes the mean across the exact recorded seed set, with an explicit deterministic tie break. It saves all candidate summaries, the selected run IDs and a digest of the experiment snapshot. Further tuning records under that experiment ID are then rejected.
A test result is a separate record that must reference the saved selection ID, a selected run and that run’s checkpoint digest. The registry rejects a result submitted before selection, a nonselected checkpoint and a duplicate final evaluation. The selection table is never reordered using test scores. Evaluate all selected seeds under the locked protocol and report their test results without choosing a favorite afterward.
These are workflow guardrails inside an editable local database. They cannot prove that a person never looked at test labels elsewhere, that the supplied metric was computed honestly, or that the recorded seed plan preceded training. For stronger assurance, use independent test access, reviewable timestamps and a preregistered protocol. A local hash is an integrity aid, not an external attestation.
Make checkpoint identity more precise than a filename
A checkpoint should identify the exact bytes evaluated and the rule that selected them. Save epoch or step, validation metric, selection direction and early-stopping policy. A latest checkpoint and a best-validation checkpoint serve different purposes. Reusing model.pt after another training run breaks provenance even if the path stays the same.
For resumable neural training, weights alone may be insufficient. Depending on the framework, continuation can require optimizer and scheduler states, random-number-generator states, mixed-precision scaler state and the data-sampler position. Preserve the environment and deterministic settings, and state which aspects of resumption you actually tested. Exact bitwise equality across platforms is a stronger claim than obtaining comparable scientific conclusions.
Hash the saved bytes and verify them before evaluation or reuse. The bundled add command checks each artifact against its declared SHA-256, and verify rehashes the local files later. Relative paths must remain within the supplied artifact root, including after resolving symbolic links. This guards common mix-ups and accidental edits. It cannot authenticate an artifact when both the file and its recorded hash are maliciously replaced.
The demonstration checkpoints are small JSON placeholders with obvious fictional labels. They are not model weights and must not be loaded as a trained classifier. Real checkpoints, dataset permissions and retention policies belong to the researcher’s environment; no private research data are included here.
Count the search cost, including unsuccessful attempts
Keep wall-clock elapsed time separate from CPU process time, accelerator allocation time, peak memory and storage. CPU time can exceed elapsed time when multiple cores work concurrently. GPU-hours based on allocation are different from integrated device utilization. State the measurement source, hardware and whether the number is measured, estimated or unavailable.
Report both a representative completed run and the broader search cost. Failed attempts, discarded settings, preprocessing, repeated evaluation and external pretraining can materially change the resource story. The NeurIPS checklist explicitly asks for compute information beyond the final reported experiments and for an explanation of what error bars represent. These reporting questions are useful even outside a conference submission. [3]
The fictional small configuration takes 48 seconds across its successful attempts plus a six-second failed attempt, for 54 fictional wall seconds in total. A completed-only view would hide that overhead. The example wide configuration totals 103 fictional wall seconds, including its failed seed. The lab keeps these totals fixed while you filter the ledger, so the visible subset cannot silently redefine the cost denominator.
Do not convert these teaching numbers into monetary cost, energy or carbon claims. Such estimates require rates, measurement intervals, machine configuration and other assumptions not provided here. The tracker’s own CPU execution is real, but the stored training costs are authored example values. The labels distinguish those two facts.
Choose a tracker for the workflow you actually need
MLflow organizes tracking around runs, with parameters, metrics and artifacts, and provides UI and API search. A local deployment is possible; shared hosting is a separate operational choice. It is a natural fit when the team wants a common run interface and programmatic queries. Add HSI-specific provenance and selection rules explicitly rather than assuming automatic logging captures them. [4, 5]
DVC connects experiments to a Git-oriented project workflow. Its comparison commands expose parameters, metrics and dependencies, and can export an experiment table or compare plots. This fits work where data versions, pipeline definitions and reviewable repository changes are already central. Ensure the relevant artifacts are actually tracked and retained; a version reference does not make missing bytes reappear. [6]
Weights & Biases supports grouping runs by shared purpose and distinguishing job types such as preprocessing, training and evaluation. Those concepts can separate seed families from execution stages in a collaborative workspace. Check the current product’s storage, access and deployment requirements before sending research data to any hosted service. No W&B account is required for this tutorial. [7]
The bundled SQLite ledger is deliberately narrower than those products. It needs no account, network connection or third-party Python package, and its policy is small enough to inspect. It lacks live dashboards, distributed ingestion, an artifact store, permissions, scheduler integration and experiment orchestration. Use it to learn the contract or support a small local study; do not confuse its compactness with a production platform.
Inside the registry explorer: fixed evidence, changeable views
The browser explorer shows the same ten fictional records exported by the Python registry. Eight attempts completed and two failed; one failed attempt was retried successfully. Native controls filter by configuration, terminal status and a bounded text query. The run table includes seed, score, time, failure reason and retry linkage. Export downloads the visible records together with the fictional-data disclosure.
The configuration comparison remains based on the full experiment. Dots show individual completed seeds, the central mark shows the mean, and the interval shows one sample standard deviation. The numeric table gives the same values and explicitly marks the incomplete group. A separate zero-baseline cost chart includes every attempt. Filtering the ledger does not recompute those comparison values.
This separation is intentional. A search for “completed” can be useful for inspection but dangerous if it also removes failed costs or changes which seeds appear in a publication table. The explorer states the aggregate scope beside the chart. Copy link preserves the table filters; Reset restores the full ledger. No uploaded dataset, external analytics service or account connection is involved.
The downloadable source includes the terminal-record CLI, deterministic example generator, JSON records, checksum-bearing artifacts and automated tests. Python 3.10 or later is sufficient for the registry. Node 20 or later runs the browser-core tests. The browser is a view over exported examples; only the Python verifier reads and rehashes local artifact files.
Offline registry explorer · fictional records
Keep the failed attempt in the story
All scores, costs, scene identifiers and checkpoints below are fictional teaching examples. No HSI classifier was trained and no training time was measured.
Ten attempts, eight completed, two failed. The small configuration has three completed seeds; the wide configuration is missing seed 33. Its higher partial mean does not make it eligible under the recorded three-seed rule.
Full-experiment comparison
Fixed scope: all ten attempts, planned seeds 11, 22 and 33. Ledger filters below do not change these summaries.
○ Completed seed · ◆ Mean · line: one sample SD, not a confidence interval · * Incomplete seed set
| Configuration | Seeds | Mean | Sample SD | Failed | All-attempt seconds | Eligibility |
|---|---|---|---|---|---|---|
| linear | 3/3 | 0.700 | 0.020 | 0 | 25 | Complete seed set |
| small | 3/3 | 0.747 | 0.015 | 1 | 54 | Complete seed set |
| wide | 2/3 | 0.765 | 0.064 | 1 | 103 | Incomplete; missing 33 |
Inspect the attempt ledger
10 of 10 fictional attempts shown. Full-experiment summaries stay unchanged.
| Run ID | Configuration | Seed | Status | Validation F1 | Wall seconds | Failure / retry note |
|---|---|---|---|---|---|---|
| linear-11 | linear | 11 | completed | 0.680 | 8 | — |
| linear-22 | linear | 22 | completed | 0.720 | 9 | — |
| linear-33 | linear | 33 | completed | 0.700 | 8 | — |
| small-11 | small | 11 | completed | 0.750 | 15 | — |
| small-22 | small | 22 | completed | 0.730 | 17 | —; retry of small-22-failed |
| small-22-failed | small | 22 | failed | Missing | 6 | Fictional interrupted data-loader attempt |
| small-33 | small | 33 | completed | 0.760 | 16 | — |
| wide-11 | wide | 11 | completed | 0.810 | 40 | — |
| wide-22 | wide | 22 | completed | 0.720 | 43 | — |
| wide-33 | wide | 33 | failed | Missing | 20 | Fictional out-of-memory failure; score absent |
This view does not verify local artifact bytes. Download the source and use the Python verifier for checksum validation. No accounts or services are required.
Build a report someone else can audit
A useful experiment report starts with the question and allowed data access, then identifies the candidate set, selection rule and evaluation unit. Show the full attempt denominator, completed-seed counts and reasons for exclusions. Include the selected configuration and checkpoint digests, per-seed values, the definition of each metric, and exactly which variability an aggregate summarizes.
Attach a machine-readable snapshot rather than relying on a screenshot. In the example, a selection receipt preserves the candidate summaries and run IDs that supported the decision. An exported registry can be searched later for all runs with a particular data or split digest. When a mislabeled scene is discovered, that lineage makes it possible to identify affected comparisons without guessing from filenames.
Before sharing, review artifacts for sensitive information, license restrictions and unnecessary local paths. Environment captures can accidentally contain credentials or internal service URLs; raw scene metadata can reveal restricted locations. A reproducibility package should include what a reader is allowed to inspect and enough information to understand omissions, rather than uploading an entire working directory blindly.
Pineau and colleagues describe reproducibility as a community practice supported by code availability, challenges and reporting checklists. A registry is one practical component of that practice. Its value is the connection between a scientific claim and an inspectable execution history, including the experiments that did not become the headline result. [8]
Review the evidence before promoting a result
First, check identity: does the resolved configuration match its digest, and can you locate the exact dataset, split, transform and checkpoint artifacts? Second, check comparability: were candidate methods given equivalent data access, label budgets and selection opportunities? Third, check the denominator: are retries, failed seeds and excluded configurations still visible?
Next, check the decision boundary. Was the winning configuration selected using the recorded validation rule, and were final test results added only after that decision was fixed? Then check interpretation: does the spread describe initialization, resampling or independent deployment units? Are incomplete seed sets and unknown pretraining exposure stated clearly?
Finally, check recoverability. Run the verifier, execute the tests from a fresh copy of the download and inspect a small selection receipt without the original author present. If an artifact is unavailable, a protocol is ambiguous or a result cannot be reproduced, record that limitation. An honest, searchable history is more useful than a polished dashboard whose best number cannot be explained.
Workflow comparison
| Option | Useful organizing idea | What you still need to specify |
|---|---|---|
| MLflow | Runs, metrics, artifacts and UI/API search | HSI provenance, comparison cohorts and selection rules |
| DVC | Git-oriented experiments, dependencies and metric/plot comparison | Tracked inputs, artifact retention and review conventions |
| Weights & Biases | Run groups and job types for related executions | Correct grouping, access policy and scientific protocol |
| Bundled SQLite ledger | Local immutable terminal records and validation selection receipt | Live job reconciliation, real training instrumentation and separate leakage audit |
Questions
Is this another model-training pipeline?
No. The runnable code stores and audits completed, failed and cancelled run records. It complements the pipeline capstone by tracking decisions across runs.
Were the example HSI scores measured?
No. All ten records, scores, training resource costs and checkpoint placeholders are fictional. The registry operations and tests are real.
Should a failed run receive a zero score?
No. The example stores its final score as missing and preserves the failure reason and resource cost. A different budget-based evaluation policy must be explicitly defined.
Can the tracker choose a model using test accuracy?
No. Tuning records and selection accept only validation macro-F1. Separately linked test results require an existing locked selection and the selected checkpoint digest.
Does a matching checksum prove that a split is leakage-free?
No. It identifies unchanged bytes relative to a recorded digest. Spatial overlap, data access and pretraining exposure require separate scientific audits.
Do I need MLflow, DVC or a W&B account to run it?
No. The Python CLI uses SQLite and the standard library only. Those products are compared as workflow options; the tutorial does not install or connect them.
Primary references
- Liang et al. On the Sampling Strategy for Evaluation of Spectral-spatial Methods in Hyperspectral Image Classification. arXiv:1605.05829 (2016).
- Cawley and Talbot. On Over-fitting in Model Selection and Subsequent Selection Bias in Performance Evaluation. JMLR 11 (2010).
- NeurIPS Paper Checklist Guidelines: experimental detail, error bars and compute resources.
- MLflow official documentation: MLflow Tracking and run concepts.
- MLflow official documentation: searching runs through the UI and Python API.
- DVC official documentation: reviewing and comparing experiments.
- Weights & Biases official documentation: organize runs into groups and job types.
- Pineau et al. Improving Reproducibility in Machine Learning Research. JMLR 22 (2021).